YOLOv8 (Object Detection)
This case study runs YOLOv8 through the RBLN Runtime API and analyzes how model operations map to NPU commands in an ATOM™ trace.
YOLOv8 is a prominent deep learning model in object detection and can be applied across a wide range of tasks. It shows excellent performance relative to its latency and the number of parameters. YOLOv8 utilizes C2f and Spatial Pyramid Pooling Fast (SPPF) blocks as its backbone to effectively perform various tasks. Detailed information about YOLOv8 can be found in the YOLOv8 official docs.
Preliminaries
Installation
Compile Model and Activate RBLN Profiler
When using the RBLN Runtime API, set activate_profiler=True to enable the RBLN Profiler:
Extract Profiled Data with Inference
Run inference to obtain profiling data:
Alternatively, use scoped profiling methods as shown below:
Analysis of Profiled data from YOLOv8l with RBLN Profiler
Profiling Result
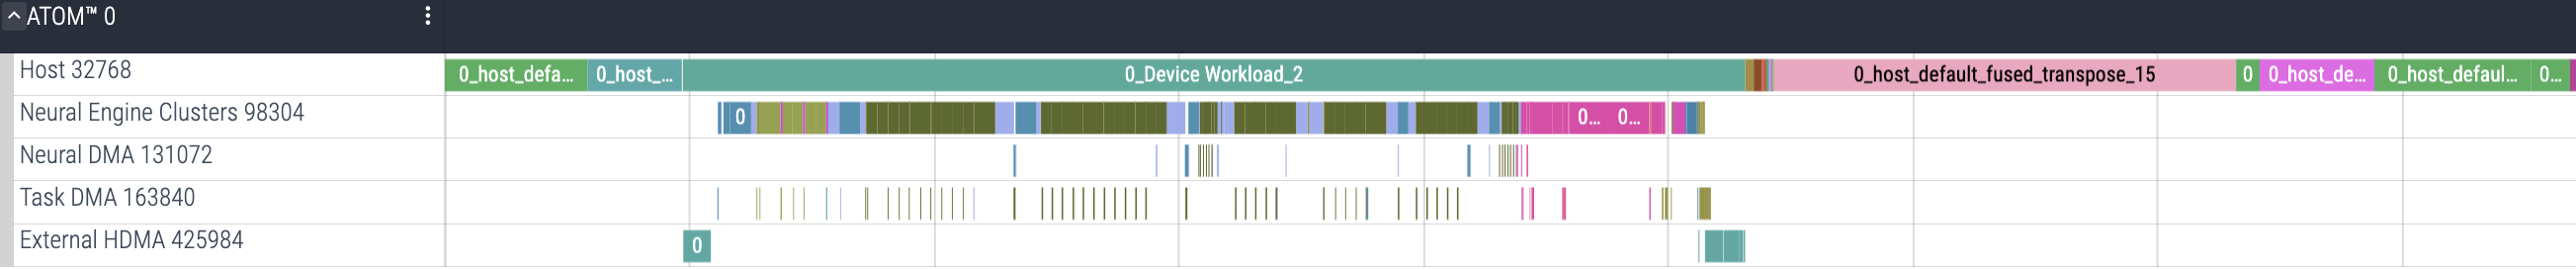
As seen in the above figure, YOLOv8l is well accelerated by ATOM™, and these operations are analyzed in detail below.
Host Command
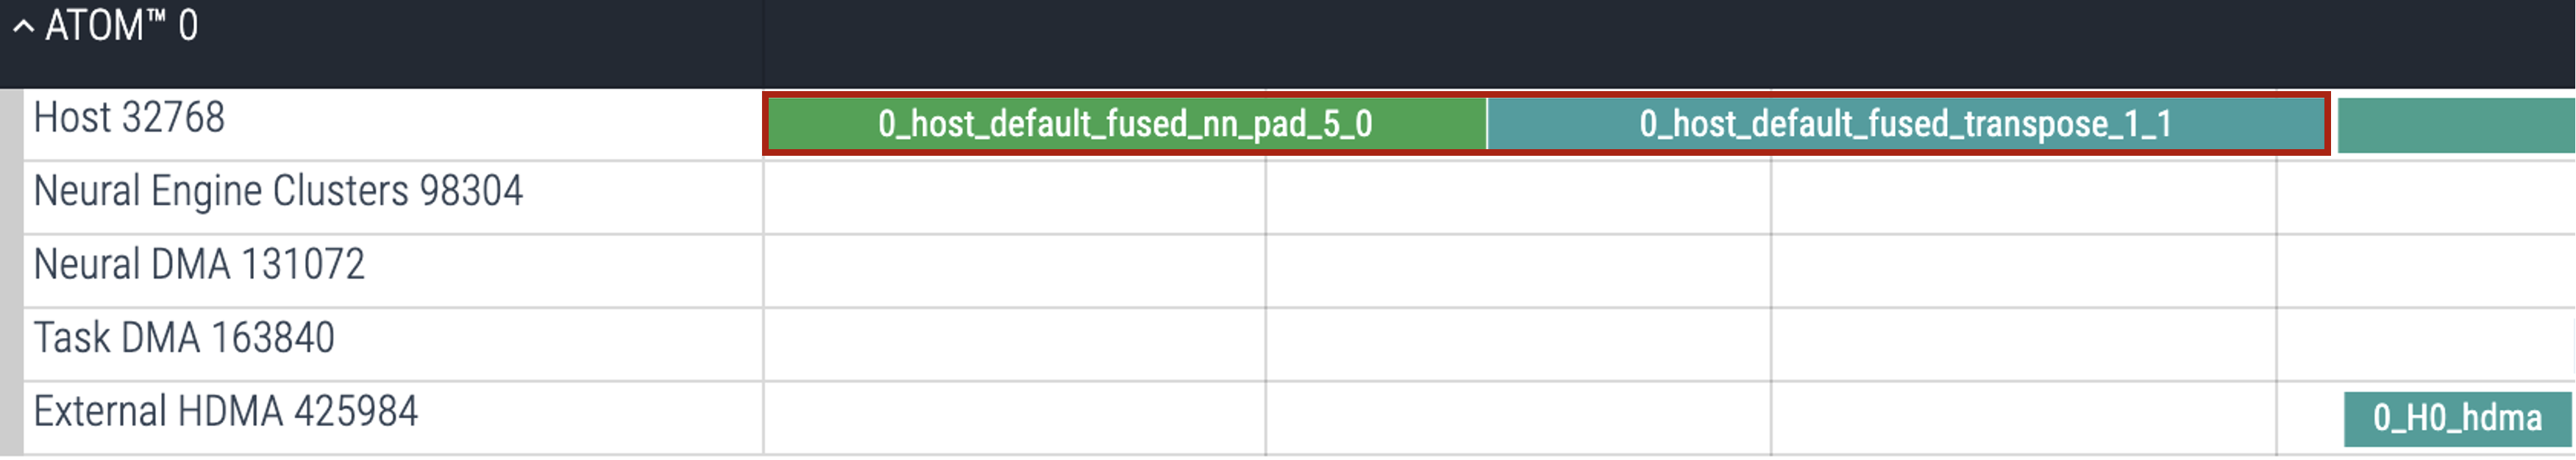
As shown in the figure above, the Host commands (0_host_default_fused_nn_pad_5_0 and 0_host_default_fused_transpose_1_1) transform input data into a format suitable for ATOM™ before the External HDMA command transfers it. Similarly, after inference, the results are sent back to the host CPU through External HDMA and are then converted into the desired output format using the corresponding Host commands. The names of Host commands are generated by internal logic and always include the host prefix.
Input Flow
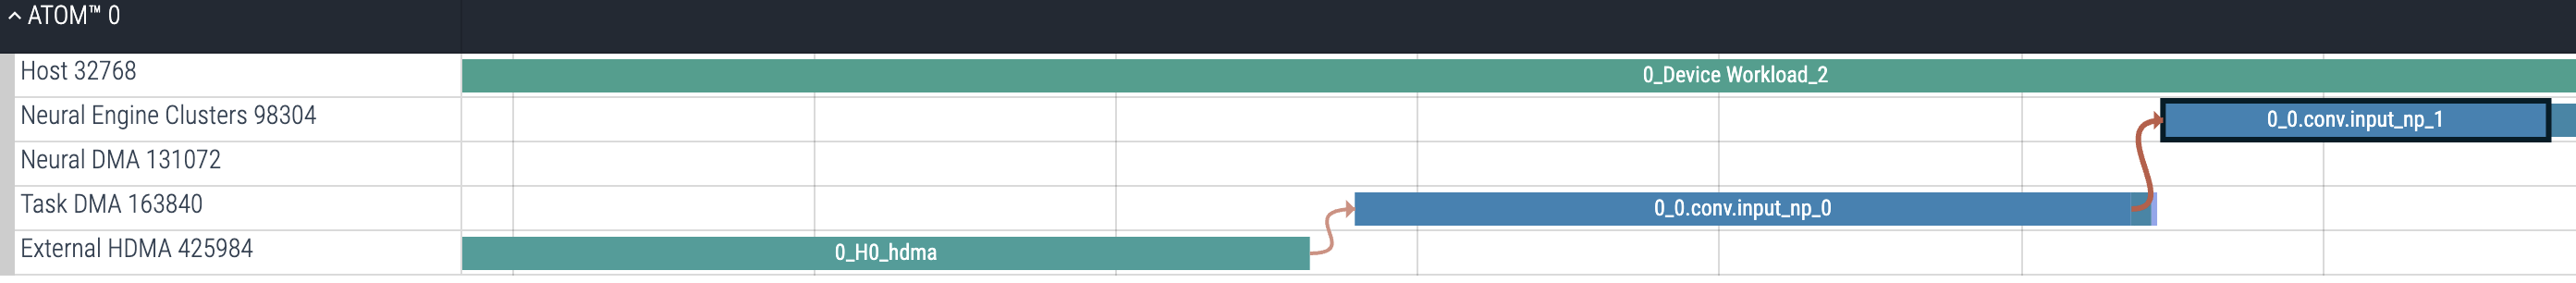
As shown in the example above, the first Neural Engine Clusters command of YOLOv8l is 0_0.conv.input_np_1. This command’s flow indicates a dependency on the immediately preceding Task DMA command (0_0.conv.input_np_0). Additionally, this dependency can also be inferred from the fact that both commands (0_0.conv.input_np_0, 0_0.conv.input_np_1) have the same name except for the index suffix. The name of these commands is derived from a combination of conv, the name of the first operation in the model, and input_np, the name assigned to the input data during compilation.
External HDMA command (0_H0_hdma). Subsequently, the input data is transferred to the shared memory using the Task DMA command (0_0.conv.input_np_0) and is then used as an operand in the Neural Engine Clusters command (0_0.conv.input_np_1). Similarly, the output data is transferred in the reverse order of the input data transmission. The Task DMA and External HDMA commands deliver the required output data from shared memory to DRAM and from DRAM to host memory, respectively.
Analysis of C2f block
Ambiguous command name
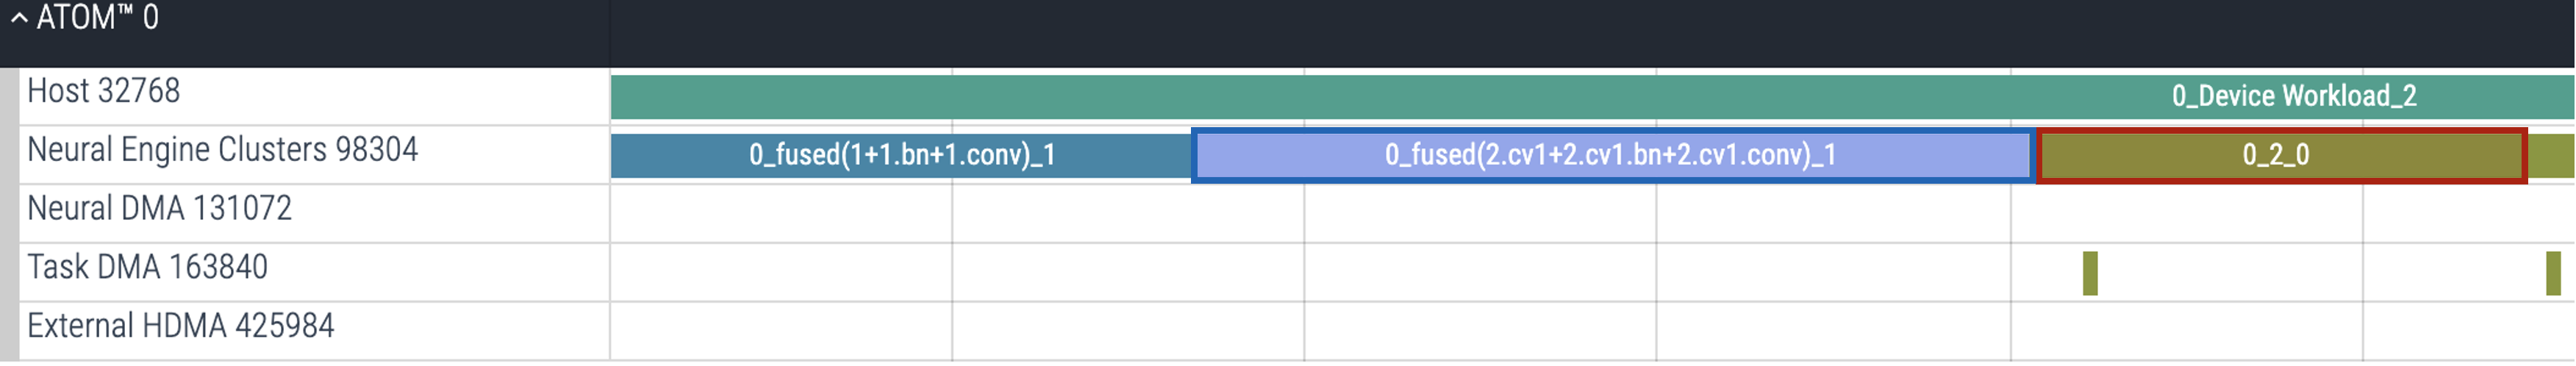
The command 0_fused(2.cv1+2.cv1.bn+2.cv1.conv)_1 in the blue box corresponds to the fused self.cv1(x) block in the PyTorch code and the first (cv1) block in the result of print(model). From this, it follows that the subsequent 0_2_0 in the red box corresponds to the .split((self.c, self.c), 1) in the PyTorch code. For detailed information about how these names are assigned, refer to Naming Policy in Detail.
Connection flow
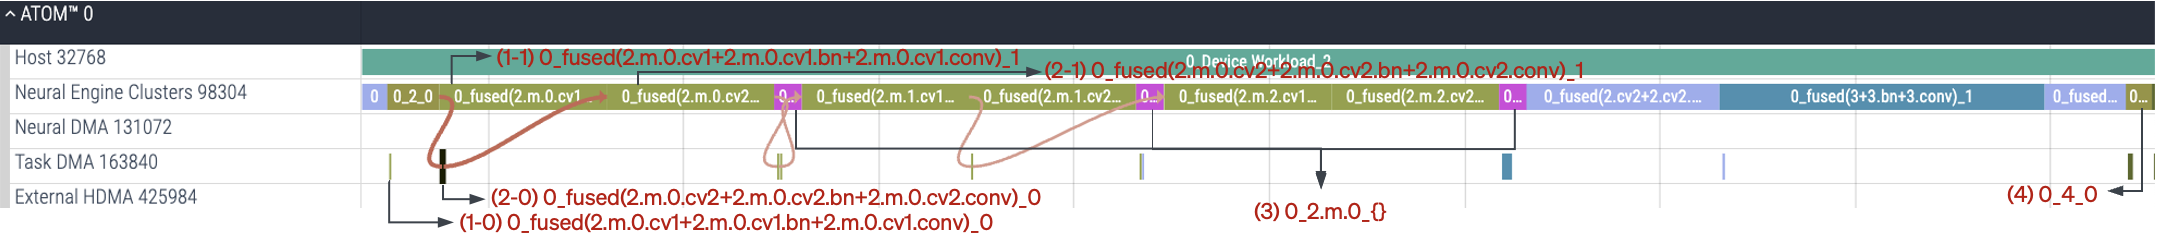
The Neural Engine Clusters commands such as (1-1) and (2-1), which come after the 0_2_0, correspond to the convolution blocks within the bottleneck operation defined by self.m in the PyTorch code. The flows between Task DMA commands (1-0, 2-0) and Neural Engine Clusters commands (1-1, 2-1) show that the Neural Engine Clusters commands need preloaded weights when they perform actual tensor operations. The command (3) corresponds to the add operation inside the bottleneck blocks, and the command (4) corresponds to the concatenation operation in the source code, self.cv2(torch.cat(y, 1)).
Device Workload
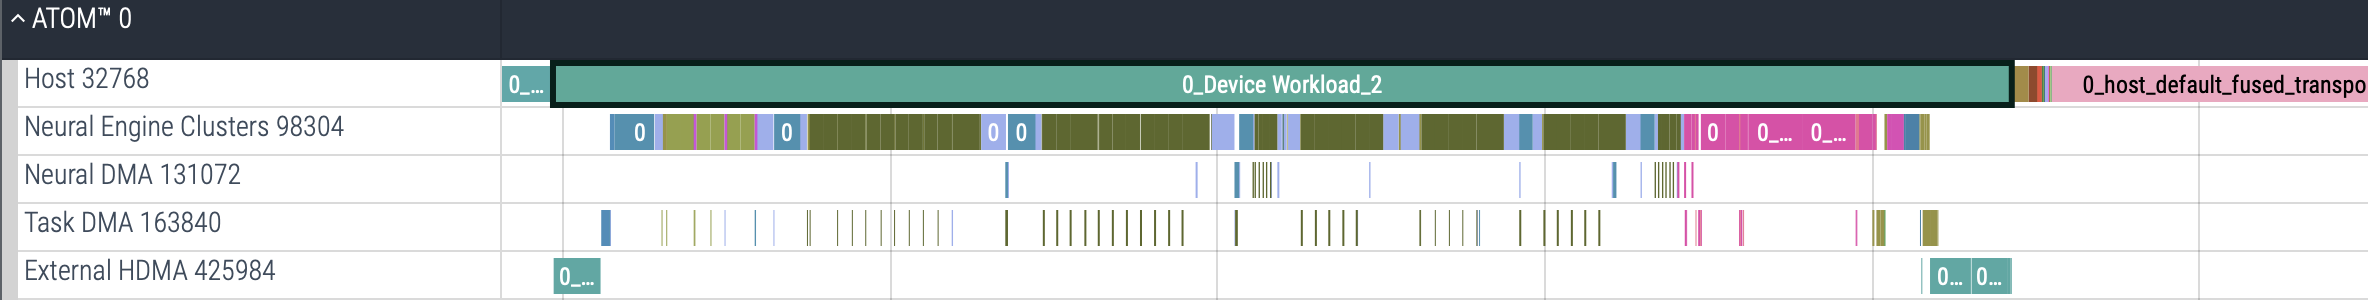
As described above, a large number of commands are processed within the device. The Device Workload of the Host command shows when the device is occupied and in use. It clearly marks the start and end of tasks performed within the device.
Profiling Overhead
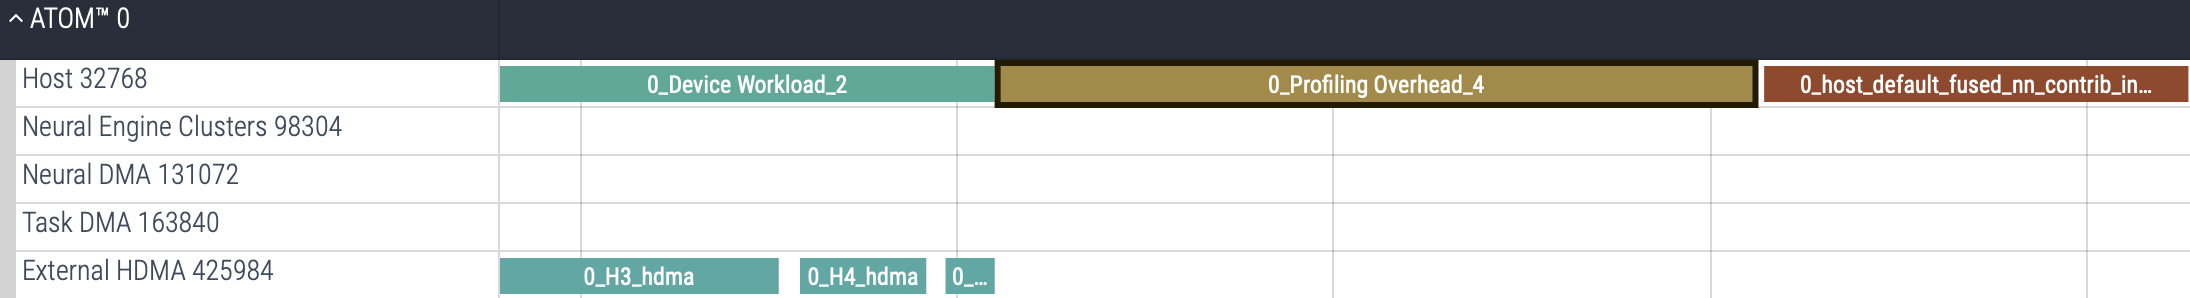
The RBLN Profiler organizes the profiled data collected from ATOM™ after Device Workload has finished. This step incurs a certain delay, which is recorded as Profiling Overhead for the Host command. Once the profiled data has been organized, additional Host commands may be processed.
References
- RBLN Profiler
- Analyzing profiler data with Perfetto
- Other profiling examples: Stable Diffusion 3 (Image Generation), Llama3-8B (Text Generation)