Stable Diffusion 3(이미지 생성)
이 사례에서는 RBLN Optimum으로 Stable Diffusion 3를 실행하고, 여러 ATOM™에 배치된 텍스트 인코더·트랜스포머·VAE 등 하위 모듈의 실행 과정을 분석합니다.
Stable Diffusion 3(SD3)는 다양한 최첨단 텍스트 기반 이미지 생성 모델들을 능가하는 멀티모달 디퓨전 트랜스포머(Multimodal Diffusion Transformer, MMDiT) 모델입니다.
SD3와 같은 일부 모델들은 여러 개의 하위 모듈로 구성되어 있습니다. 이 모델의 모든 하위 모듈을 단일 ATOM™에 불러오면 메모리 용량을 초과할 수 있습니다. 이러한 문제를 해결하기 위해 하위 모듈별로 런타임을 생성하고 이를 여러 대의 ATOM™에서 나누어 처리하는 방식으로 메모리 사용량을 최적화할 수 있습니다.
RBLN 컴파일러와 프로파일러는 하위 모듈 여러 개를 사용하는 상황에서 여러 대의 ATOM™을 사용하는 컴파일과 프로파일링을 지원합니다. 예를 들어, RBLN 프로파일러는 SD3의 전체 하위 모듈에 대한 프로파일링 데이터를 생성할 뿐만 아니라 텍스트 인코더, 디퓨전 트랜스포머, VAE(Variational AutoEncoder) 등 하위 모듈 각각에 대한 프로파일링 데이터 또한 생성합니다.
사전 준비
설치
| $ cd rbln-model-zoo/ATOM/huggingface/diffusers/text-to-image/stable_diffusion_3_t2i
$ pip3 install -r requirements.txt
|
모델 컴파일 및 프로파일러 활성화
| # 예시 텍스트: "a photo of a cat holding a sign that says hello world"
$ python3 compile.py
$ RBLN_PROFILER=1 python3 inference.py
|
환경 변수 대신 RBLN Optimum API를 사용할 때에는 각 모듈에
"activate_profiler": True 인자를 전달하면 RBLN 프로파일러를 활성화할 수 있습니다:
| # rbln-model-zoo/ATOM/huggingface/diffusers/text-to-image/stable_diffusion_3_t2i/inference.py
...
pipe = RBLNStableDiffusion3Pipeline.from_pretrained(
...
rbln_config={
...
"text_encoder": {"device": 0, "activate_profiler": True},
"text_encoder_2": {"device": 0, "activate_profiler": True},
"text_encoder_3": {"device": 1, "activate_profiler": True},
"transformer": {"device": 0, "activate_profiler": True},
"vae": {"device": 0, "activate_profiler": True},
},
)
...
|
또한, 분석하고자 하는 일부 하위 모듈에 대해서만 프로파일링을 수행할 수도 있습니다. 이 경우, 프로파일링에서 제외할 하위 모듈에 "activate_profiler": False 인자를 전달합니다.
추론을 통한 프로파일링 데이터 추출
권장 사항
RBLN 프로파일러는 디퓨전 과정의 모든 반복을 트레이스(trace)하고, 이 때문에 프로파일링 시간이 매우 길어질 수 있습니다. inference.py 파일의 인자를 num_inference_steps=1과 같이 설정하면 프로파일링 결과를 더 빨리 얻을 수 있습니다.
| # rbln-model-zoo/ATOM/huggingface/diffusers/text-to-image/stable_diffusion_3_t2i/inference.py
...
# Generate image
image = pipe(
# prompt, num_inference_steps=28, height=1024, width=1024, guidance_scale=7.0
prompt,
num_inference_steps=1,
height=1024,
width=1024,
guidance_scale=7.0,
).images[0]
...
|
모델 추론을 통해 프로파일링 데이터를 얻을 수 있습니다:
| # rbln-model-zoo/ATOM/huggingface/diffusers/text-to-image/stable_diffusion_3_t2i/inference.py
...
# Generate image
image = pipe(
# prompt, num_inference_steps=28, height=1024, width=1024, guidance_scale=7.0
prompt,
num_inference_steps=1,
height=1024,
width=1024,
guidance_scale=7.0,
).images[0]
...
|
또는 구역이 지정된 프로파일링 메서드를 사용하여 프로파일링 데이터를 얻을 수 있습니다:
| # rbln-model-zoo/ATOM/huggingface/diffusers/text-to-image/stable_diffusion_3_t2i/inference.py
...
from rebel.profiler import profile
with profile(output_dir="./profile_out"):
# Generate image
image = pipe(
# prompt, num_inference_steps=28, height=1024, width=1024, guidance_scale=7.0
prompt,
num_inference_steps=1,
height=1024,
width=1024,
guidance_scale=7.0,
).images[0]
...
|
RBLN 프로파일러 기반 SD3의 프로파일링 데이터 분석
프로파일링 결과
| # https://github.com/huggingface/diffusers/blob/78bc824729f76a14ff2f211fc7f9a31e5500a41e/src/diffusers/pipelines/stable_diffusion_3/pipeline_stable_diffusion_3.py#L343
class StableDiffusion3Pipeline(DiffusionPipeline, SD3LoraLoaderMixin, FromSingleFileMixin):
...
def encode_prompt(
...
):
...
prompt_embed, pooled_prompt_embed = self._get_clip_prompt_embeds(
prompt=prompt,
...
)
prompt_2_embed, pooled_prompt_2_embed = self._get_clip_prompt_embeds(
prompt=prompt_2,
...
)
...
t5_prompt_embed = self._get_t5_prompt_embeds(
prompt=prompt_3,
...
)
...
negative_prompt_embed, negative_pooled_prompt_embed = self._get_clip_prompt_embeds(
negative_prompt,
...
)
negative_prompt_2_embed, negative_pooled_prompt_2_embed = self._get_clip_prompt_embeds(
negative_prompt_2,
...
)
t5_negative_prompt_embed = self._get_t5_prompt_embeds(
prompt=negative_prompt_3,
...
)
...
return prompt_embeds, negative_prompt_embeds, pooled_prompt_embeds, negative_pooled_prompt_embeds
|
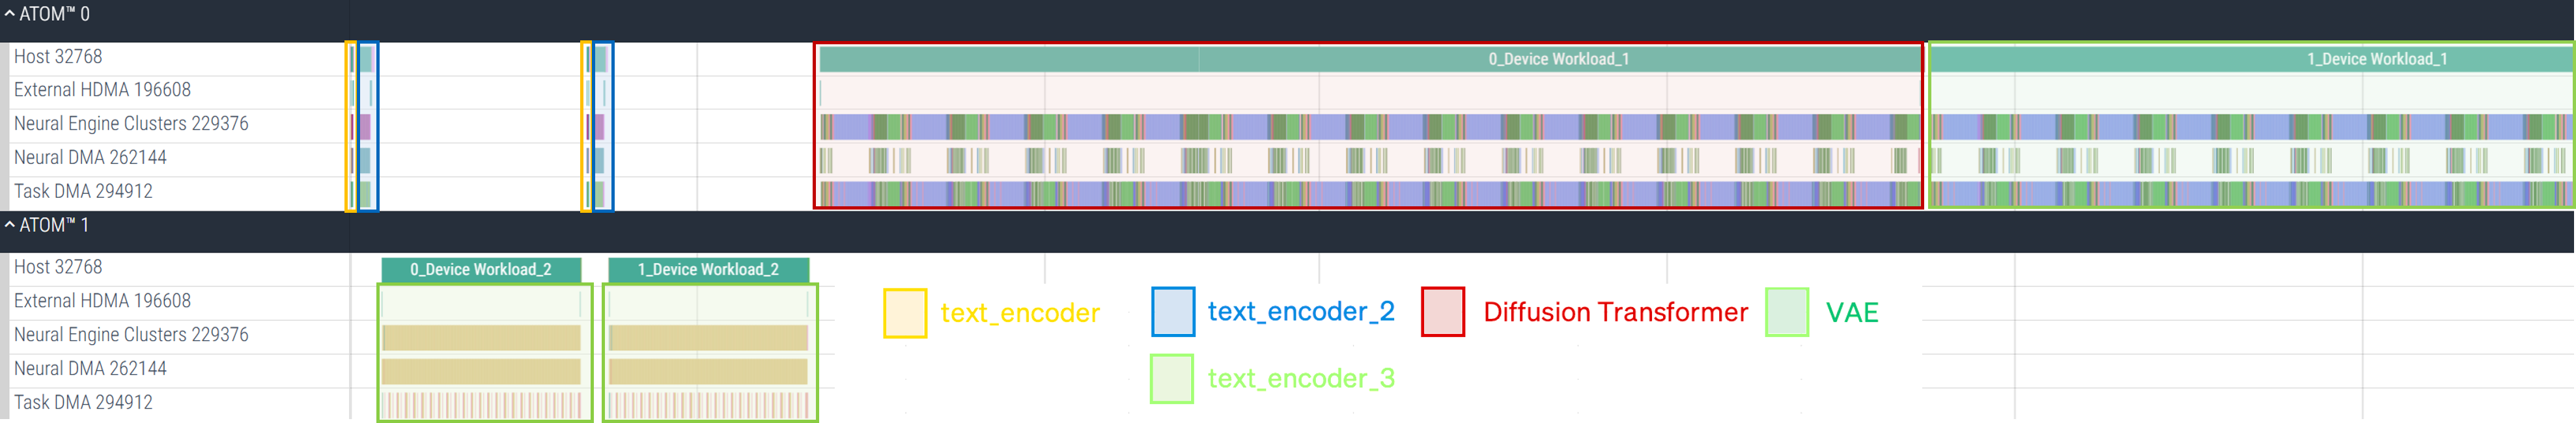
SD3는 세 개의 텍스트 인코더(text_encoder, text_encoder_2, text_encoder_3)를 하위 모듈로 포함합니다. pipeline_stable_diffusion_3.py 코드의 encode_prompt 함수에 따르면, 각 텍스트 인코더는 지시문과 부정 지시문을 생성하기 위해 두 번씩 실행됩니다. RBLN 프로파일러는 각 텍스트 인코더가 실행될 때마다 하나의 *.pb 파일을 생성하기 때문에, encode_prompt 과정에서는 총 6개의 *.pb 파일이 생성됩니다. 뒤이어 트랜스포머는 정해진 횟수(num_inference_steps)만큼 반복해서 실행되고, 이에 따라 해당 횟수만큼의 *.pb 파일이 생성됩니다. 마지막으로, VAE 디코더가 최종 이미지를 생성하고, 하나의 *.pb 파일이 생성됩니다. 또한 전체 추론 과정에 대한 모든 트레이싱 정보들을 담은 *.pb 파일이 생성되며, 이 파일은 모든 하위 모듈들의 프로파일링 결과를 순차적으로 보여줍니다.
Note
SD3의 모든 하위 모듈을 단일 ATOM™에 불러오면 메모리 제한을 초과할 수 있습니다. 이 문제를 해결하기 위해 text_encoder_3는 그 외 하위 모듈들과는 다른 ATOM™(ATOM™ 1)에서 실행됩니다. 이때, 여러 대의 ATOM™을 사용하는 경우에도 Host 명령어는 공통된 하나의 호스트에서 동작하기 때문에 루트(root)로 결정된 ATOM™(ATOM™ 0)에서만 생성됩니다.
디바이스 배치에 대한 자세한 설명은 예제 inference.py의 주석에 있습니다.
큰 연산에 대한 분할 처리
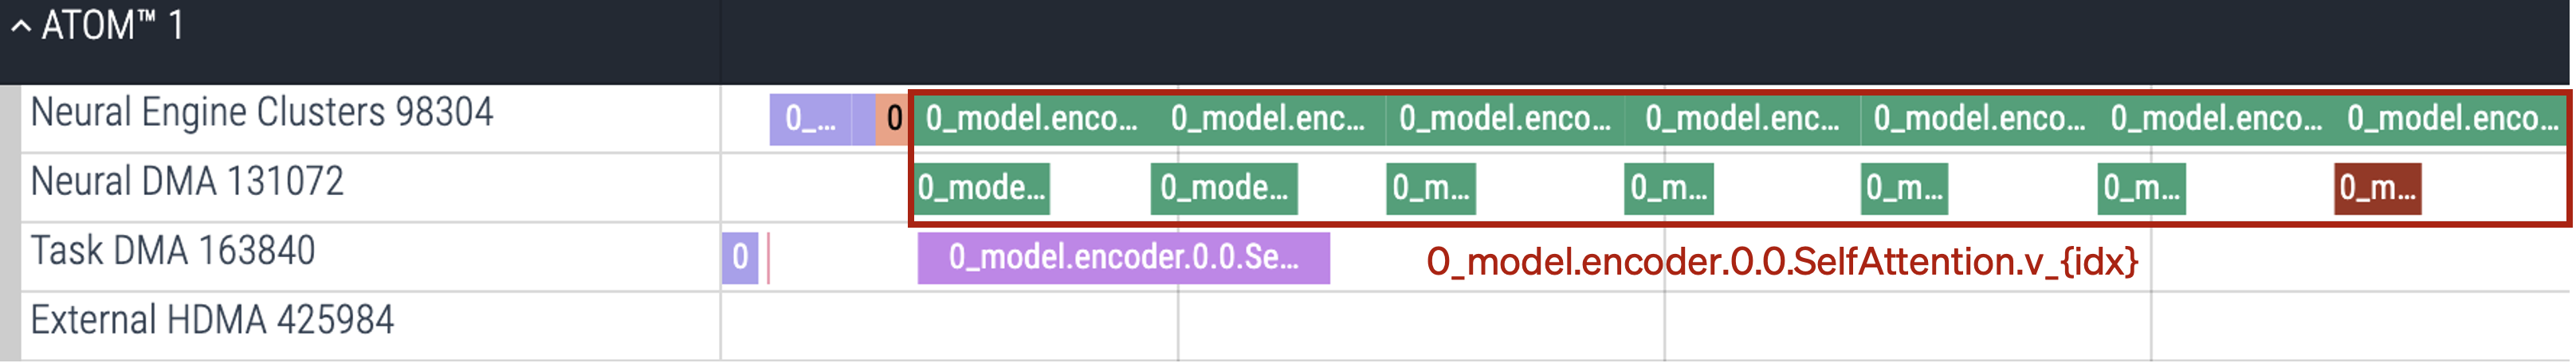
RBLN 컴파일러는 분할 처리를 적용하여 큰 연산들을 효율적으로 최적화합니다. 위의 프로파일링 결과에서 확인할 수 있는 것처럼, 분할된 연산은 동일한 이름을 공유하고 command_index를 통해 구분할 수 있습니다.
참고 자료