Stable Diffusion 3 (Image Generation)
This case study runs Stable Diffusion 3 with RBLN Optimum and analyzes the execution of submodules, including the text encoders, transformer, and VAE, placed across multiple ATOM™ devices.
Stable Diffusion 3 (SD3) is a Multimodal Diffusion Transformer (MMDiT) model, which outperforms various state-of-the-art text-to-image generation models.
Some models, such as SD3, consist of multiple submodules, and loading all submodules onto a single device may occasionally exceed the device's memory capacity. To optimize memory utilization, devices can be assigned individually to the runtime created for each submodule.
The RBLN Compiler and the RBLN Profiler support multi-device compilation and the generation of profiled data for models with multiple submodules. For example, the RBLN Profiler can generate multiple profiled data files for each submodule in SD3, such as the text encoders, the diffusion transformer, and the VAE (Variational AutoEncoder). It can also generate a single profiled data file that includes all submodules of SD3.
Preliminaries
Installation
Compile Model and Activate RBLN Profiler
Or, set "activate_profiler": True to enable the RBLN Profiler in each module:
To profile only a subset of submodules, set "activate_profiler": False for the submodules to exclude from profiling.
Extract Profiled Data with Inference
Recommendation
The RBLN Profiler captures all iterations of the diffusion process, which may result in extended profiling times. To obtain quicker profiling results, set num_inference_steps=1 in inference.py.
Run inference to obtain profiling data:
Alternatively, use scoped profiling methods as shown below:
Analysis of Profiled Data from SD3 with RBLN Profiler
Profiling result
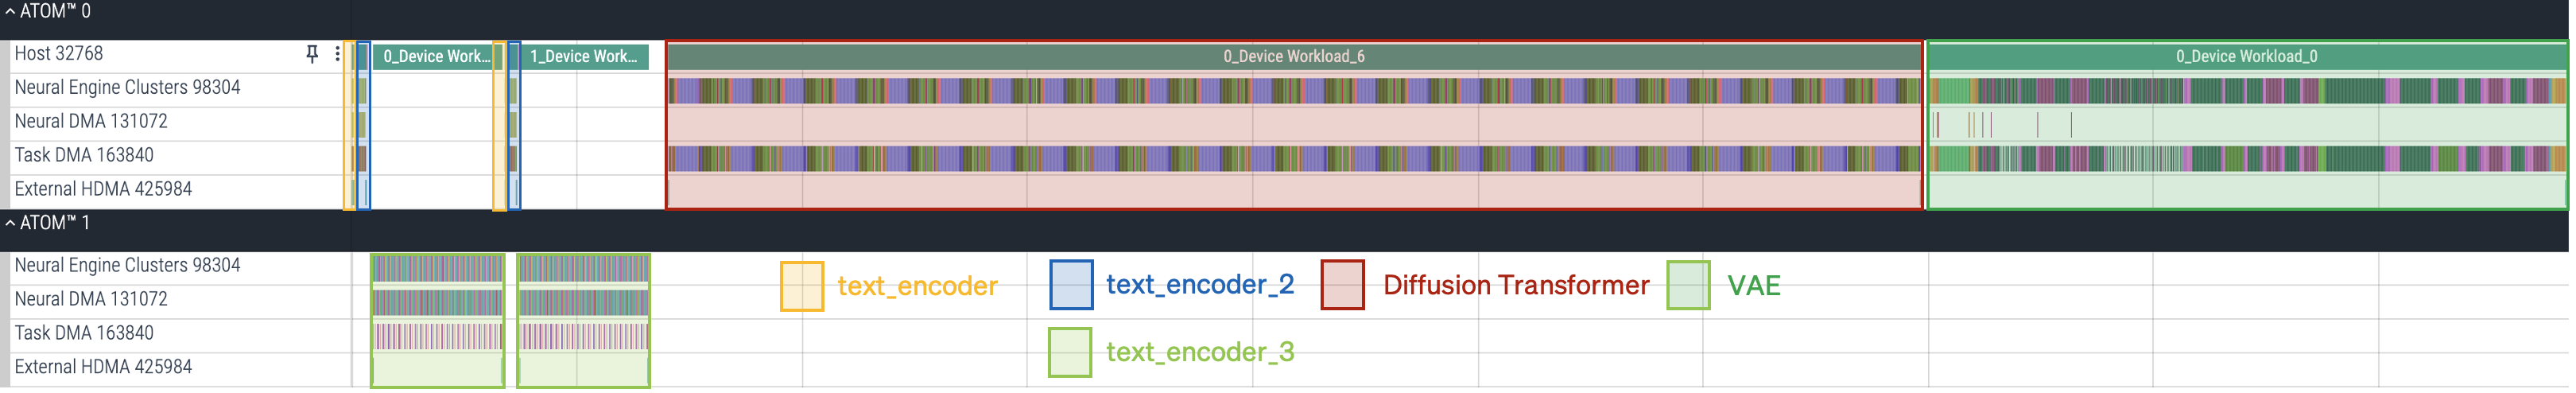
SD3 has three text encoders (text_encoder, text_encoder_2, and text_encoder_3). According to the encode_prompt function in the pipeline_stable_diffusion_3.py code, each text encoder is called twice to generate prompts and negative prompts. Since the RBLN Profiler generates a single *.pb file when each text encoder is called, this encode_prompt process results in the generation of six *.pb files. Additionally, since the diffusion transformer is called for a specified number of iterations (num_inference_steps), one *.pb file is generated for each iteration. Finally, when the VAE decoder produces the final image, a single *.pb file is generated. A full log *.pb file is also generated to represent the entire tracing information, displaying the sequential profiling results of all submodules.
Note
Loading all submodules of SD3 on a single device may exceed the device's memory capacity. To address this, text_encoder_3 is executed on a separate device (ATOM™ 1). Furthermore, since the multi-device setup is mounted on a single host, Host commands are generated only on the root device (ATOM™ 0).
The comments in the example's inference.py explain this device placement in detail.
Tiling large operations
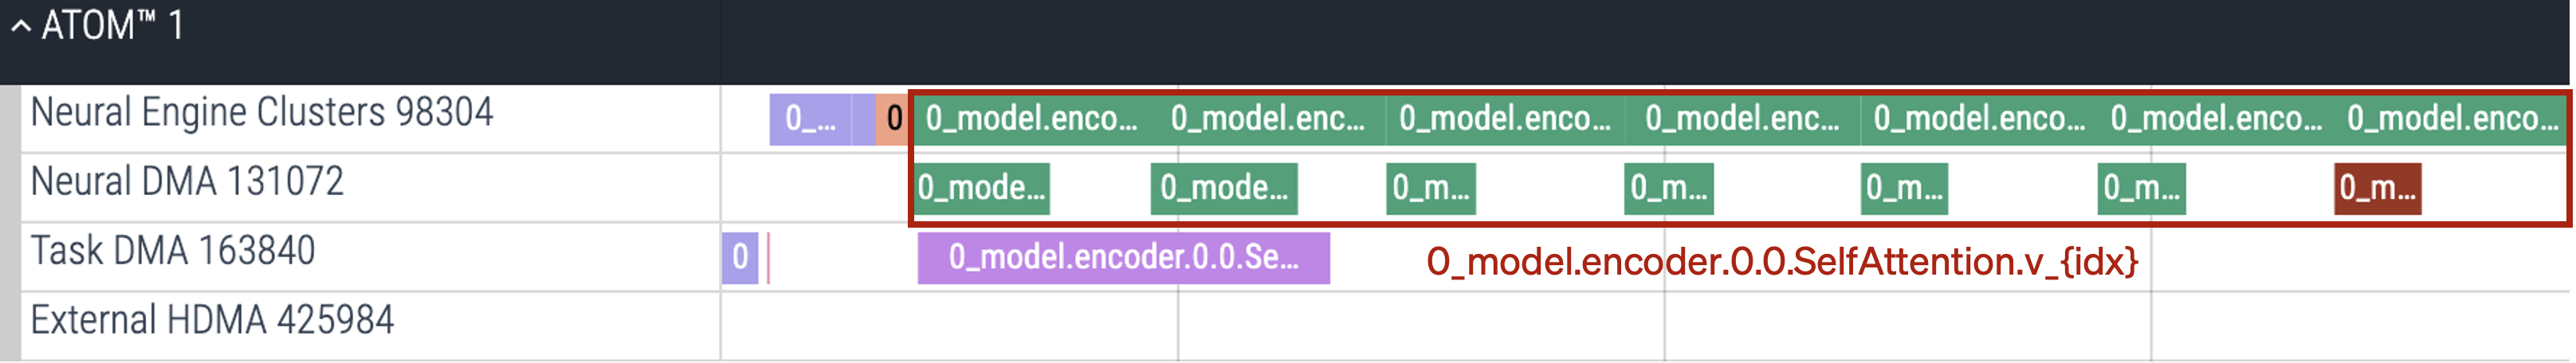
The RBLN Compiler efficiently optimizes large operations by applying the tiling method. As seen in the profiling results above, the tiled operations share the same name but have different indices.
References
- RBLN Profiler
- Analyzing profiler data with Perfetto
- Other profiling examples: YOLOv8 (Object Detection), Llama3-8B (Text Generation)